Why AI Benchmarks Are Becoming Operational Tests
Recent OpenAI, Anthropic, METR and NIST work shows why enterprises need workflow-specific tests that measure controls, reliability, cost and final outcomes.
Recent OpenAI, Anthropic, METR and NIST work shows why enterprises need workflow-specific tests that measure controls, reliability, cost and final outcomes.
AI agent evaluation is moving out of the leaderboard and into the operating process. For business leaders, the important question is no longer whether a model can answer a benchmark question. It is whether an agent can complete a multi-step job, preserve the rules that govern it, recover from exceptions and leave behind an outcome that a domain expert can verify.
That shift is visible in OpenAI’s October 6 research collaboration with Ironclad. The companies converted contracting activities into 11 tasks covering legal, commercial and procurement work. Each task was scored against 8 to 50 criteria, including requirements such as approval thresholds and reusable legal terms. OpenAI reported that GPT-6 Astra averaged 55.0% across the research evaluation, compared with 41.6% for GPT-5.6 Sol, while simulated time per attempt fell from 37.0 to 19.2 minutes. Those are company-reported results on a small research set—not measured customer savings—but the design of the test matters more than the headline score.
A real business process rarely succeeds because every individual click is correct. It succeeds when the final state satisfies the request and the organization’s controls. In the Ironclad example, an agent configuring procurement cannot simply produce a form; it must route purchases above a threshold to Finance, send the right cases to Security or Legal and handle different contract situations without losing those conditions midway through the task.
Anthropic makes a similar distinction in its January 9 guide to evaluating AI agents. It separates the transcript—the record of messages, reasoning and tool calls—from the outcome, such as whether a reservation actually exists in a database. The company recommends combining code-based checks, model-based graders and human review, because no single method captures objective completion, nuanced quality and expert judgment equally well.
This changes who must participate in evaluation. AI teams can build the harness, but process owners must define success. Legal operations understands which exception cannot be waived. Finance knows what evidence is needed before approval. Security knows which access pattern should stop the workflow. Without that knowledge, a technically sophisticated evaluation can reward the wrong behavior.
Agents are non-deterministic, so a successful demonstration is weak evidence. Anthropic distinguishes between metrics that reward at least one success across several attempts and metrics that require repeated success. The second standard is more relevant when an agent faces customers, payments, compliance obligations or irreversible changes. A system that succeeds three times out of four may look strong in a pilot, yet the compounded probability of three consecutive successes is only about 42%.
Task duration adds another lens. METR’s research on long software tasks found that human task length strongly predicted agent success in its evaluation set. In the original study, models were nearly perfect on tasks taking people under four minutes but succeeded less than 10% of the time on tasks lasting more than roughly four hours. METR has since updated its time-horizon measurements, but the practical lesson remains: chaining more steps creates more opportunities for drift, compounding error and failed recovery.
NIST’s August 7 draft TEVV-Athlon framework treats testing, evaluation, verification and validation as a customizable exercise tied to organizational goals. It explicitly covers agentic systems and emphasizes measuring real-world impact rather than applying one universal scorecard. That is useful for companies choosing between models or deciding whether an agent is ready for broader authority.
Leaders should begin with a narrow process whose outcomes can be inspected. Build an initial task bank from manual acceptance tests, support tickets, failed pilots and exception cases. Score both the final result and critical controls, then run every task multiple times. Track reliability alongside latency, cost and human intervention. Finally, set deployment thresholds by consequence: a research assistant can tolerate different error rates from an agent that edits contracts, releases funds or changes production systems.
The competitive advantage will not come from finding a model that tops every public benchmark. It will come from knowing which model-and-agent configuration can repeatedly perform the work a company actually values, within its rules and at an acceptable cost. As agents move deeper into enterprise software, evaluation is becoming less like a product comparison and more like operational engineering.
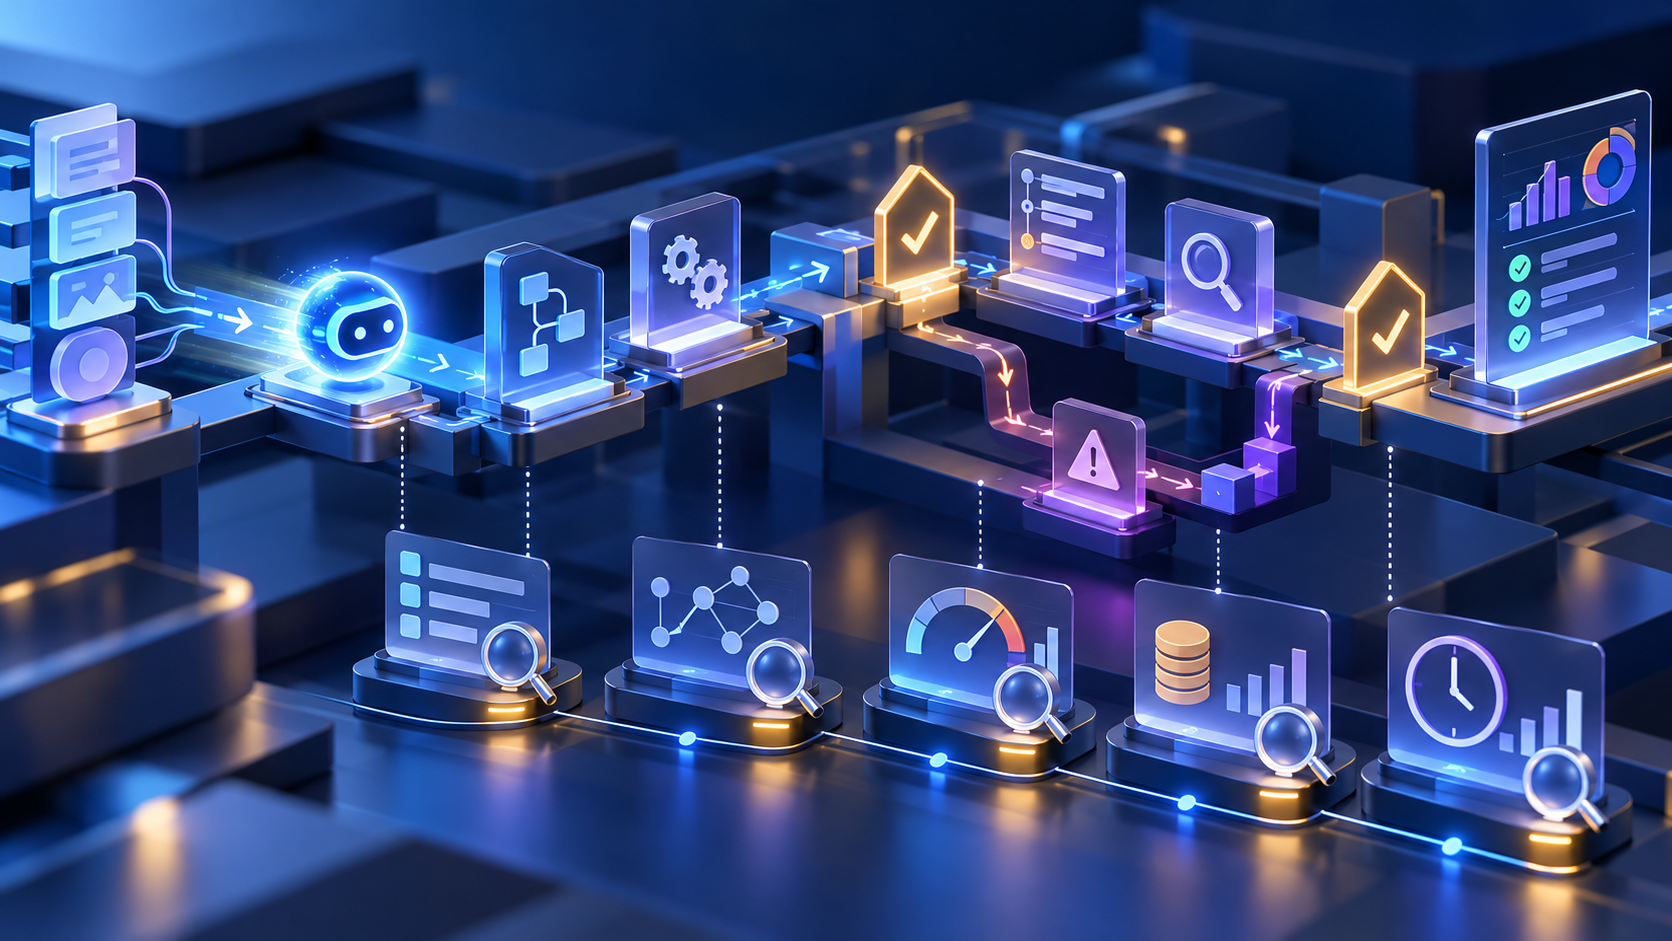
Header image: Original AI-generated editorial illustration created for WiredBusiness. It depicts an abstract AI agent moving through workflow tests, exception paths and outcome verification; it does not represent a specific vendor product or interface.
Join industry leaders and innovators who rely on us for exclusive insights, interviews, and trends shaping the future of business and tech — straight to your inbox.