Why Agentic AI Is Turning Inference Into a Scheduling Problem
llm-d 1.0 shows how distributed routing, context reuse and multi-tenant flow control are becoming core infrastructure for production agentic AI.

llm-d 1.0 shows how distributed routing, context reuse and multi-tenant flow control are becoming core infrastructure for production agentic AI.
Agentic AI changes the shape of inference traffic. A conventional chatbot sends a prompt and waits for one answer. An agent can call a model repeatedly, invoke tools, fork work into parallel tasks, pause, and return with much of the same context. That pattern makes model serving less like a simple web endpoint and more like a scheduling system.
The release of llm-d 1.0 on October 20, 2026 makes that transition visible. The open-source project combines distributed routing, cache management, traffic control and operational tooling for large-model inference. Its significance is not that every enterprise should self-host models. It is that production inference now needs explicit decisions about where requests run, which work gets priority and how expensive context is reused.
Traditional load balancers treat replicas as broadly interchangeable. Large-model inference is different because each replica may hold a valuable key-value cache created while processing earlier tokens. Sending a later turn to the wrong replica can force the system to recompute the same context, adding latency and consuming accelerator capacity.
Google Cloud says agent traffic increasingly arrives in bursts, shares long prefixes and fans out across tools. In its llm-d 1.0 announcement, the company described a demonstration in which 1,000 sandboxed agents shared one endpoint across multiple model servers and accelerator types. Google attributed the result to cache-aware routing, tiered cache and flow control that kept interactive requests responsive while agent loops generated bursts. That is a vendor demonstration, not a universal benchmark, but it illustrates why replica selection now depends on state rather than connection count alone.
Inference itself can be divided into different kinds of work. “Prefill” processes the prompt and builds its cache; “decode” generates output tokens. llm-d can place those stages in separate pools and route the same request through both. It also supports moving cached context among accelerator memory, host memory and storage, so capacity can be managed across a fleet instead of being trapped on one device.
IBM Research’s release analysis frames the operational problem as combining five techniques: prefix-cache-aware routing, cache offloading, batch optimization, prefill/decode disaggregation and wide expert parallelism. IBM’s claim is that version 1.0 adds the “day two” controls required when traffic changes, hardware fails, software is upgraded or tenants compete for the same resources.
This is consistent with the Kubernetes Gateway API Inference Extension, whose stated goals include model-aware routing, per-request criticality, safe model rollouts and load balancing driven by model metrics. The emerging architecture separates the public model endpoint from the scheduler that chooses the most suitable backend.
When employees, customer-facing applications and autonomous agents share infrastructure, not every request can have equal priority. A burst from a background research agent should not stall a real-time support workflow. Conversely, idle capacity should be usable for batch jobs rather than sitting reserved.
llm-d 1.0 introduces fairness and priority controls that queue work by tenant and service class. Google also describes an asynchronous processor that can run lower-priority jobs when spare capacity is available. For platform leaders, this turns service-level objectives, quotas and cost centers into scheduling inputs. The useful governance question is no longer only “which model is approved?” It is also “which workload can consume which pool, at what priority, under what budget?”
The Cloud Native Computing Foundation lists llm-d as a sandbox project supporting intelligent scheduling across NVIDIA, AMD and Intel GPUs as well as Google TPUs. That breadth can reduce dependence on one accelerator or cloud, but portability still requires validated configurations, compatible model servers, networking and observability.
The lesson mirrors WiredBusiness’s analysis of serverless portability: a common execution model lowers migration friction, but data, identity and operations remain attached to real infrastructure. Model-serving teams must test performance on their own prompts, hardware mix and traffic patterns rather than inherit a headline benchmark.
A production scorecard should include time to first token, token-generation latency, queue time by priority, cache-hit rate, accelerator utilization and cost per completed business task. Teams should also track how many sessions are disrupted during upgrades, how often work is rejected under saturation and whether one tenant can degrade another.
Those measures belong beside the ownership and migration controls discussed in WiredBusiness’s guide to AI model lifecycle management. A replacement model can change context size, memory demand and serving behavior; lifecycle approval is incomplete if the inference platform cannot absorb those changes safely.
Managed APIs remain the practical choice for many workloads. Self-hosted or distributed inference becomes more attractive when an organization has sustained demand, sensitive data, specialized models, heterogeneous hardware or a need to enforce workload priorities directly. Even then, the comparison should include engineering effort, resilience and upgrade discipline—not accelerator price alone.
The strategic shift is that inference is becoming its own platform layer. As agents multiply model calls and carry more state between them, competitive advantage will depend less on exposing a model endpoint and more on scheduling context, capacity and priority with discipline.
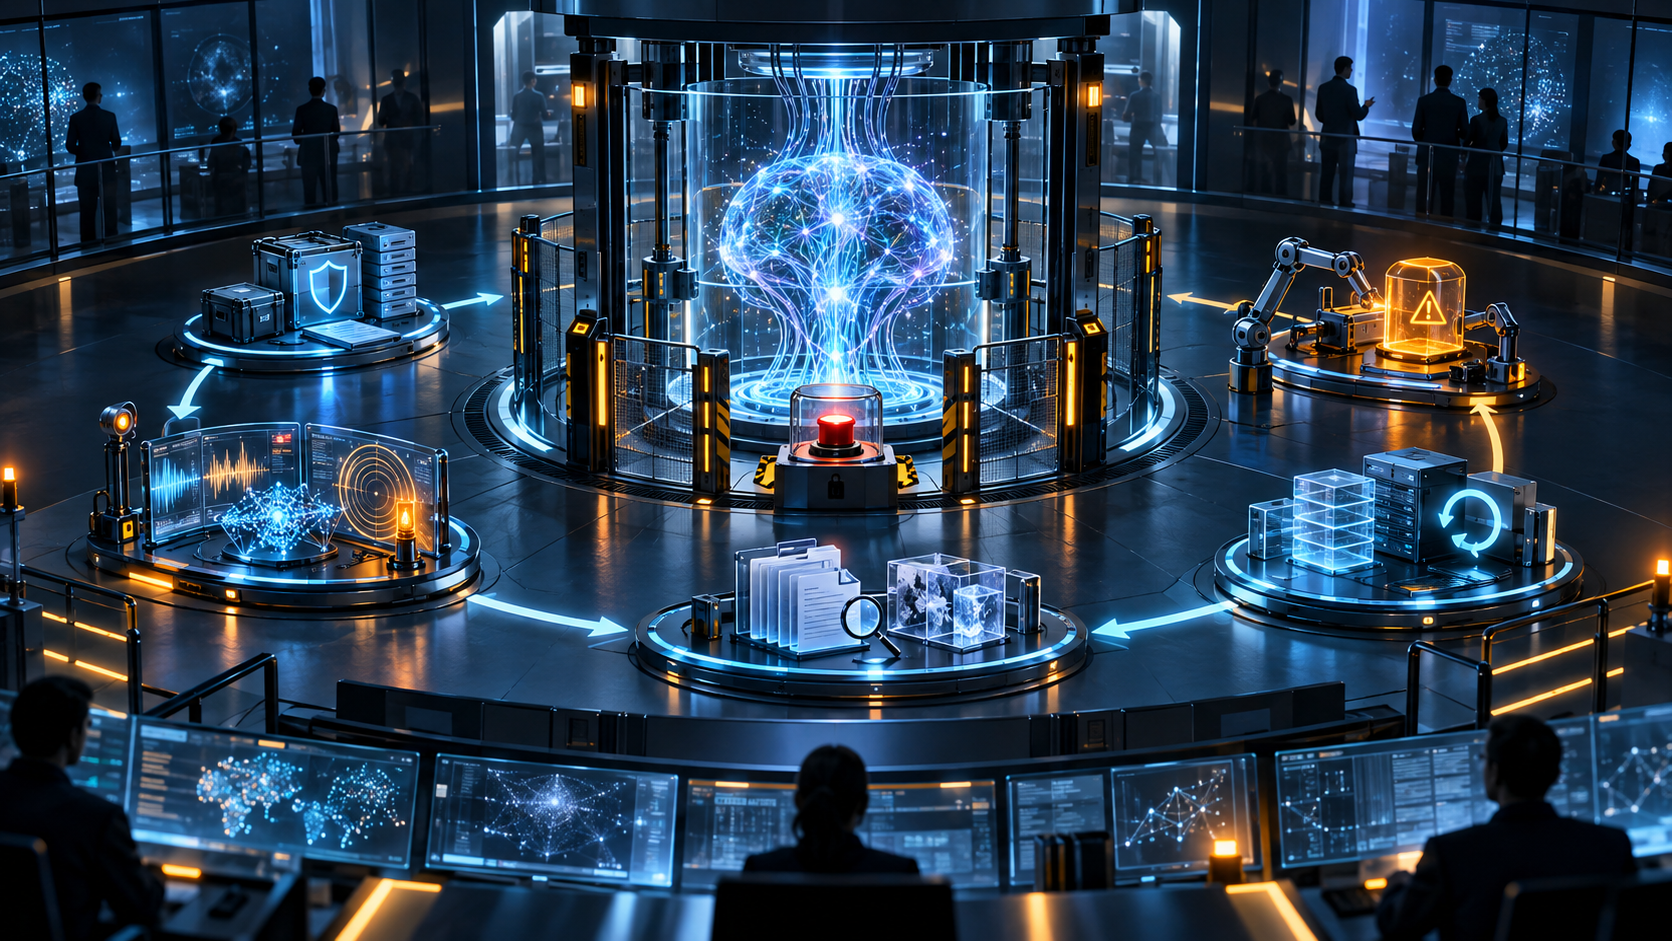
Header image: Original AI-generated editorial illustration created for WiredBusiness. It represents distributed inference scheduling and does not depict a specific vendor product or production environment.
Join industry leaders and innovators who rely on us for exclusive insights, interviews, and trends shaping the future of business and tech — straight to your inbox.