Why Generative Interfaces Are Becoming a Software Layer
OpenAI, Google, Oracle and CopilotKit developments show how dynamic interfaces are becoming a new software layer built from trusted components, portable protocols and bounded actions.
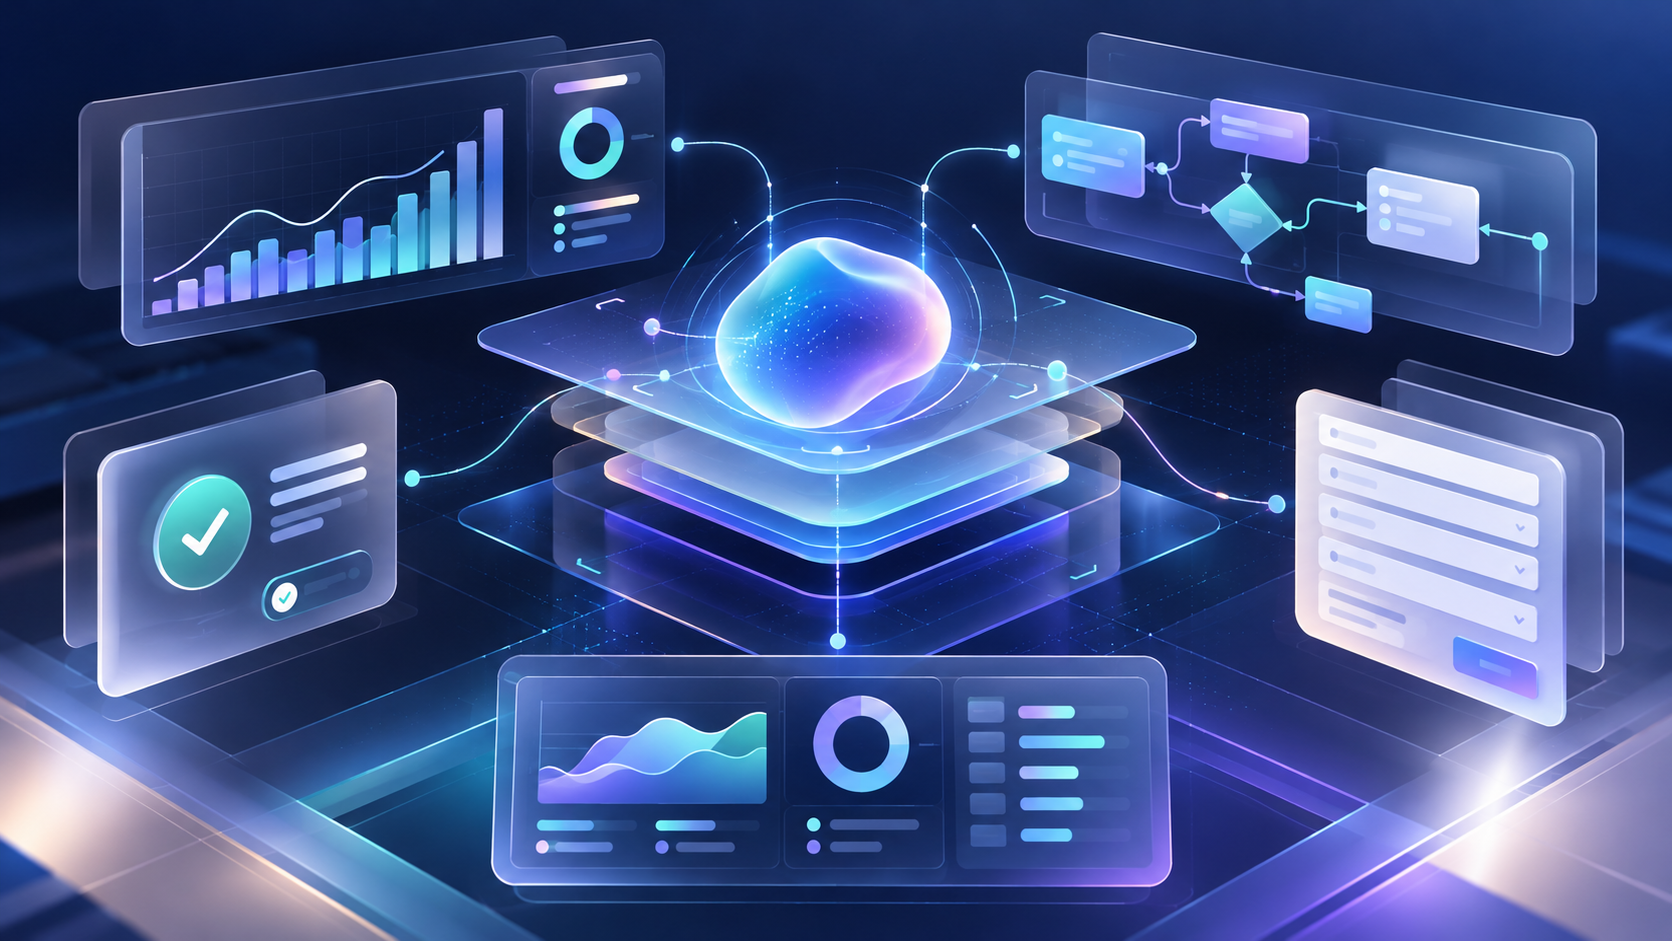
OpenAI, Google, Oracle and CopilotKit developments show how dynamic interfaces are becoming a new software layer built from trusted components, portable protocols and bounded actions.
Analysis — Software interfaces have traditionally been designed before a user arrives: teams choose the screens, controls and navigation paths, then ask people to learn the product’s structure. A new wave of generative-interface systems is testing a different model. Instead of returning only prose, an AI system can assemble charts, forms, calculators and workflow controls around the task at hand.
The shift became more visible on October 7, 2026, when OpenAI introduced Intelligent UI in ChatGPT. The company says GPT-6 can combine text, visuals and interactive elements, selecting a format according to the question. Two days later, CopilotKit released Open Intelligent UI, an open-source implementation intended to bring similar behavior into third-party applications. These are product announcements, but together they point to a broader design question for enterprise software: what happens when the interface becomes a runtime output rather than a fixed container?
A conventional business application exposes a menu of functions. A generative interface can begin with intent, then present the controls and information needed for that particular job. A procurement manager might receive a comparison table and an approval button; a service agent might see an account timeline, suggested actions and an editable response. The underlying systems of record do not disappear. What changes is the presentation layer between those systems and the person doing the work.
OpenAI describes a native, streamable component library and a compiler that processes an interface while the model generates it. That detail matters because it separates generative UI from the looser idea of letting a model write an arbitrary web page. Reusable components can impose visual consistency, accessibility behavior and technical boundaries while still allowing the model to choose an appropriate composition.
For product leaders, the design system therefore becomes more than a collection of reusable buttons and color rules. It becomes a catalog of approved actions the model can combine. Each component can carry permissions, validation and audit behavior. A generated refund control, for example, should still enforce the same limits as a manually designed refund screen.
CopilotKit argues that generative UI should use an organization’s existing components, real data and user context. Its October 9 release spans approaches from controlled composition, in which an agent selects from approved components, to more open generation. That spectrum creates a governance decision: the more freedom a model has to create an interface, the more isolation, testing and review the surrounding platform needs.
The interface layer is also attracting open specifications. In April, the Google A2UI team described version 0.9 as a framework-agnostic approach for agents to declare interface intent while clients render trusted native components. The release included a shared web core and support for React, Flutter and Angular renderers.
In March, Oracle, Google and CopilotKit outlined how three specifications could work together: Oracle’s Agent Spec defines agent behavior and workflows, AG-UI carries the interaction stream, and A2UI describes what the user sees and touches. Their stated goal is portability across agent runtimes, interface frameworks and observability tools.
That layered model is significant for buyers. If it matures, a company could change an agent runtime without rebuilding every frontend, or introduce a new client while preserving the same approved component catalog. The practical benefit would be lower switching costs and fewer bespoke integrations—not simply a more animated chat window.
Generative interfaces will be useful only when they reduce the distance between a request and a completed action. A dynamic dashboard that looks impressive but sends users into three separate systems has not changed the workflow. The stronger use cases will combine explanation, context and a bounded action in one surface while retaining clear approval points.
Enterprises should measure task completion time, correction rates, accessibility outcomes and the number of human handoffs—not the number of interfaces generated. They should also log which components were shown, what data informed them and which actions users accepted. Without that record, troubleshooting a changing interface will be harder than troubleshooting a static one.
A sensible pilot starts with one repetitive, reversible workflow and a small catalog of approved components. Product, security and operations teams can define which data the model may expose, which actions require confirmation and what happens when the system is uncertain. The interface should fall back gracefully to a stable view rather than improvising through an error.
The strategic implication is not that every screen will vanish. Fixed interfaces remain valuable for frequent, regulated or precision-heavy work. The more likely future is hybrid: stable application structure for orientation and control, with task-specific surfaces assembled inside it. In that model, interface architecture becomes a new software layer—one that translates intent into a governed combination of data, explanation and action.
Image: Original editorial illustration generated for WiredBusiness.
Join industry leaders and innovators who rely on us for exclusive insights, interviews, and trends shaping the future of business and tech — straight to your inbox.